OKF vs Schema: What's the Difference?
OKF and Schema.org structured data both make content machine-readable, but they do different jobs. How they compare, with code, and when to use each.
Two things with the same shape
Ever since I wrote up what OKF is, one question keeps coming back to me in some form or another. Do I need OKF if I already have schema?
I get why people ask. Put the two side by side and they look like cousins. Both make content easier for machines to understand. Both lean on structure and metadata. Both come up whenever someone talks about the machine-readable web.
But asking whether you need both is a bit like asking whether a library needs a catalogue and books. They do different jobs, and the gap between those jobs is wider than it looks at first.
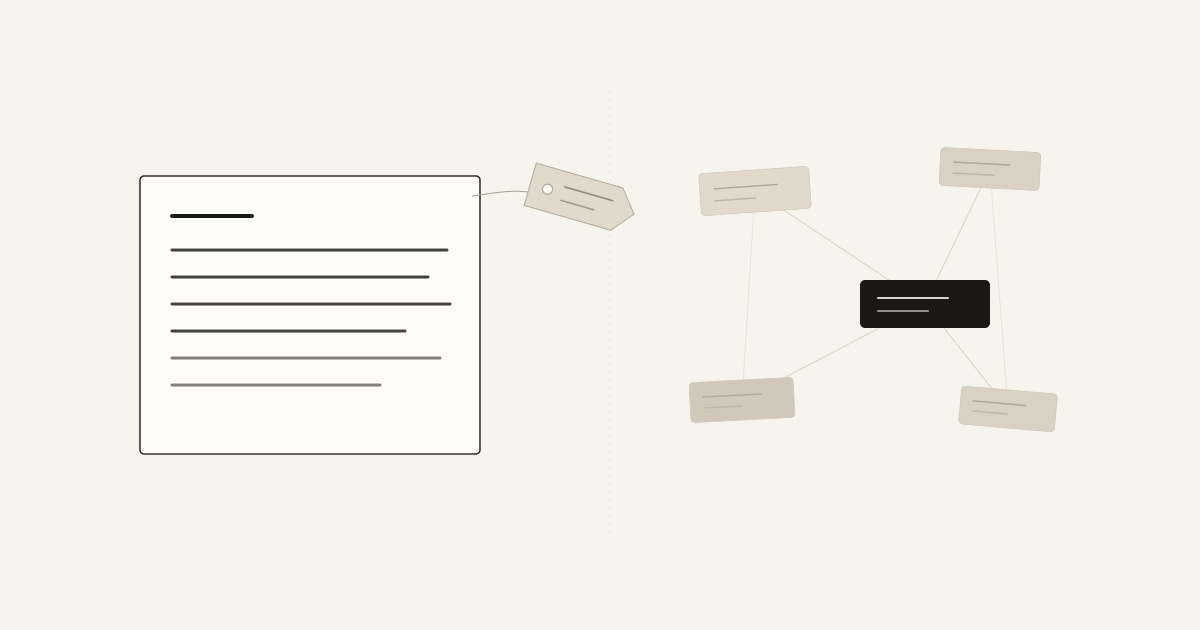
Schema tells a machine what a page is. OKF hands over the knowledge itself, in a form people and agents can read, follow, and pass around. The explainer had the short version of this. This is the long version, with the code.
Clearing up the word “schema”
Before comparing anything, there is a naming problem worth fixing, because it muddies half the conversations I see.
When most people in SEO say “schema,” they mean Schema.org structured data, usually written as JSON-LD. Those are two separate things that happen to travel together. Schema.org is a shared vocabulary: types, properties, and relationships like Article, Person, Product, Organization, author, and datePublished. JSON-LD is one format for writing that vocabulary into a page. You can also use Microdata or RDFa, though Google recommends JSON-LD.
So when I say schema in this post, I mean Schema.org structured data as most websites actually implement it. The real comparison is OKF against that, and has nothing to do with JSON as a format.
What schema actually does
Schema is metadata. You have a page, the page has content, and schema adds a machine-readable description of that content.
Take a recipe page. A person glancing at it picks up a lot in a second. It’s a recipe, it takes 35 minutes, it has a 4.8 rating from 12 reviews, and a specific person wrote it. A crawler has to work all of that out from the HTML. Structured data hands it the labels directly.
{
  "@context": "https://schema.org",
  "@type": "Recipe",
  "name": "Chicken Curry",
  "author": {
    "@type": "Person",
    "name": "Aditya Raj Singh"
  },
  "totalTime": "PT35M"
}
The interesting part is what this code leaves out. It doesn’t contain the recipe. It doesn’t contain the paragraphs on the page. You couldn’t lift it out and use it as a knowledge base. All it does is tell a machine what the content on the page represents.
Google describes structured data as a way to help its systems understand a page and make it eligible for richer search appearances, and it is careful to say those appearances are never guaranteed. Schema answers one question, and answers it well: what is this?
What OKF actually does
OKF starts from the opposite end. Instead of tucking metadata inside a web page, it represents knowledge as a folder of markdown files, each with YAML frontmatter on top and ordinary links to other concepts. If you want the full walkthrough of the format, the explainer covers it. The short version: the spec is at v0.2, the only field every concept must have is type, and everything else is up to you.
A simple concept looks like this.
---
type: Article
title: How I Migrated From WordPress to Astro
description: What changed when I moved my site to Astro.
resource: https://example.com/blog/astro-migration/
tags: [astro, wordpress, web]
---

# How I Migrated From WordPress to Astro

The full article content goes here.

This article connects to:
[Astro](/concepts/astro.md)

[WordPress](/concepts/wordpress.md)
Look at what changed. The YAML describes the concept, the way schema would. But the markdown body underneath is the content itself, and the links tie it to other concepts in the bundle. Schema describes the page. OKF carries a copy of what the page knows.
That puts it much closer to a portable knowledge corpus than a metadata layer. Google frames it broadly on purpose: a vendor-neutral format for metadata, context, and curated knowledge, with no runtime, database, or AI framework attached.
The comparison, in one table
This is the version of the comparison I actually find useful.
| Schema.org structured data | OKF | |
|---|---|---|
| Primary purpose | Describe web content | Represent knowledge |
| Where it lives | Usually inside the HTML page | Markdown files in a bundle |
| Typical format | JSON-LD, Microdata, RDFa | Markdown + YAML frontmatter |
| Main question | ”What is this?" | "What is this knowledge, and how does it connect?” |
| Contains the full content? | Usually no | Yes, in the markdown body |
| Relationships | Structured properties and linked entities | Markdown links between concepts |
| Main audience | Search engines and structured-data consumers | People, agents, systems, indexes |
| Tied to a web page | Usually yes | No |
| Search features | Supports eligibility for some Google features | Not a rich-result format |
| Portable as a knowledge corpus | Not its purpose | Yes |
| Maturity | Mature, widely deployed | New, currently v0.2 |
If you only keep one line from it: schema is a label, OKF is a package.
One article, both ways
The difference gets clearer with a single piece of content run through both.
Say you publish an article about Kubernetes. The HTML page holds the article. The schema on that page might tell a machine something like this.
This is a BlogPosting.
The headline is X.
The author is Aditya.
It was published on Y.
The image is Z.
Useful, and exactly what a search engine wants. Now here is an OKF version of the same article.
---
type: Article
title: Kubernetes Explained
resource: https://example.com/kubernetes/
---

# Kubernetes Explained

[full article content]

See also:
[Kubernetes](/concepts/kubernetes.md)
[Containers](/concepts/containers.md)
[Kubernetes Networking](/concepts/kubernetes-networking.md)
The machine now has more than a description of a page it still needs to go and read. It has the article, plus explicit pointers to the concepts around it. Same content, but a different layer entirely.
The graph is the part I care about
If you work on internal linking or topical clusters, this is where OKF gets interesting, and it’s the same point I kept coming back to in the explainer’s section on AI search.
A normal crawl can pull the words off your site and find the links. But once everything is flattened into a pile of scraped pages, the shape of your knowledge gets hard to hold onto. The model can’t easily tell that one pillar post supports four others, or that a glossary term feeds a product page.
OKF makes those relationships part of the file itself. A bundle might look like this.
okf/
├── index.md
├── products/
│   ├── cdn.md
│   ├── api-security.md
│   └── bot-management.md
├── concepts/
│   ├── edge-computing.md
│   ├── zero-trust.md
│   └── ai-security.md
└── articles/
    ├── edge-security.md
    └── ai-security-guide.md
Link those files to each other and the result stops looking like a folder of webpages. It starts looking like a small knowledge graph you can open in a text editor.
And there’s a side effect I like even more. You can see the holes: which concepts sit alone with nothing pointing in or out, which topics have dozens of supporting pages and which have one, which parts of the site are well documented and which are close to empty. That picture is worth having before any agent ever reads the bundle.
Where each one sits in the stack
So does OKF replace schema? No. The OKF spec says plainly that it isn’t meant to replace domain-specific schemas, and even without that, the two are solving different problems.
The easiest way I’ve found to hold it in my head is to give every layer one question.
Sitemap
    ↓
Where are the URLs?

Schema.org
    ↓
What are these pages and entities?

OKF
    ↓
What is the underlying knowledge and how does it connect?

The webpage
    ↓
What does the human actually see?
There’s overlap at the edges, but nothing here pushes anything else out. A product page can carry Product structured data. That same product can live as an OKF concept. The page still sits in your sitemap. None of these are either-or choices.
Schema is not going anywhere
Every time a new AI standard shows up, a wave of posts declares the old stack dead. I’d ignore them.
Google still uses structured data to understand page content, and it’s still tied to eligibility for a long list of search features: articles, products, organizations, breadcrumbs, recipes, events, videos, and more.
There is one misconception worth killing while we’re here, though. Schema is not a ranking switch. Valid markup doesn’t guarantee a rich result, and Google says so in its own documentation. That doesn’t make schema less useful. It just means its job is narrower than SEO folklore makes it sound. It helps machines interpret your content, and that is the whole job.
The way I’d frame the split is the same one I used when writing about being cited versus being ranked. Schema serves the system that ranks you. OKF serves the system that reads you.
The problem OKF is for
The reason OKF matters now is that search engines mostly returned documents, and the systems replacing parts of them increasingly need to consume knowledge.
An AI system doesn’t always want your webpage. Sometimes it wants context: definitions, relationships, the source behind a claim, some sense of whether the thing is still current.
That last part is why v0.2 added fields for provenance, verification, freshness, lifecycle, and attestation. Once machines start generating knowledge, you have a trust problem, and the format now has room to deal with it.
Put the two next to each other and the gap is obvious. Schema can say this is an Article. OKF can say this is an Article, here is the content, here are the related concepts, here is where it came from, and here is how it was produced or checked. That second answer matters more the more agents lean on structured context.
The catch
OKF is young, and I’d rather be upfront about it. The spec is at v0.2, it moved quickly from v0.1, and it’s still changing. Google pitches it around portable, interoperable knowledge for AI systems, and nowhere does it present OKF as a replacement for how the web gets published today.
So the takeaway is definitely not “OKF is here, schema is obsolete.” The more accurate one is quieter. The web is growing another machine-readable layer, and the existing layers stay where they are.
When I would use each
Schema is the easy call. Use it whenever your content maps cleanly to a supported Schema.org type and the markup helps whatever reads it. On a normal content site that means Article or BlogPosting, Organization, Person, and BreadcrumbList, plus Product, Event, or Recipe where they fit. The one rule that matters is that the markup matches what’s visible on the page. Google explicitly warns against misleading or irrelevant structured data. For most sites, none of this is experimental. It’s just part of the stack.
OKF is a more interesting call, and it depends on how much connected knowledge you have. Documentation, product information, glossaries, research, data definitions, internal knowledge, runbooks, big content libraries. Anywhere the relationship between pieces matters almost as much as the pieces themselves. That’s close to the problem OKF was designed around in the first place: giving agents the context surrounding data and systems in a portable format.
For a five-page brochure site, there isn’t much to gain. For a site with 5,000 interlinked documents, it gets a lot more tempting. And if you want to see what your own site looks like as a bundle without writing one by hand, the OKF Bundle Generator will build one from your sitemap.
Where I’ve landed
“OKF vs schema” turned out to be the wrong question. The better one is which layer of machine understanding you’re trying to improve.
If you want search engines to understand your pages, entities, authorship, products, and breadcrumbs, Schema.org structured data is the tool. If you want to package a body of knowledge so people and AI systems can consume it, traverse it, and reason over it, that’s what OKF is for. And nothing says you have to pick.
My guess is the web ends up looking something like this.
                        Your Content

                 ┌──────────┴──────────┐
                 ↓                     ↓
          Structured metadata       Knowledge
                 ↓                     ↓
              Schema                   OKF
                 ↓                     ↓
          Search systems         Agents / AI systems
One tells the machine what it’s looking at. The other gives it what it needs to understand the thing itself.
FAQ
Is OKF the same as Schema.org? No. Schema.org is a vocabulary for describing entities and content. OKF is a format for representing knowledge with markdown, YAML frontmatter, and links between concepts. The OKF explainer covers the format in more detail.
Does OKF replace schema markup? No. Schema helps systems interpret web page content. OKF packages knowledge and context in a portable format. They stack.
Is JSON-LD the same thing as schema? No. JSON-LD is a serialization format. Schema.org is the vocabulary you write in JSON-LD, Microdata, or RDFa.
Does OKF improve Google rankings? There’s no evidence it’s a ranking signal. Google ties structured data to understanding content and eligibility for search features, and OKF sits outside that.
Should a website have both? They can happily coexist. Schema describes the page and its entities, and an OKF bundle carries the knowledge underneath and how it connects.
Schema was never going to be replaced by a folder of markdown files. What’s happening is quieter than that. The web is adding a layer for readers that aren’t people, and the sites that already label their pages well are in a good position to hand those readers the rest. Keep your schema, try a bundle, and see what the graph shows you.